Orchestration and the Native Runner
Bring your own CI. Or run it here.
Cycloid isn’t a second CI/CD tool. Every Action runs on the built-in Native Runner or in the CI you already operate, and Cycloid tracks it all in one status view.
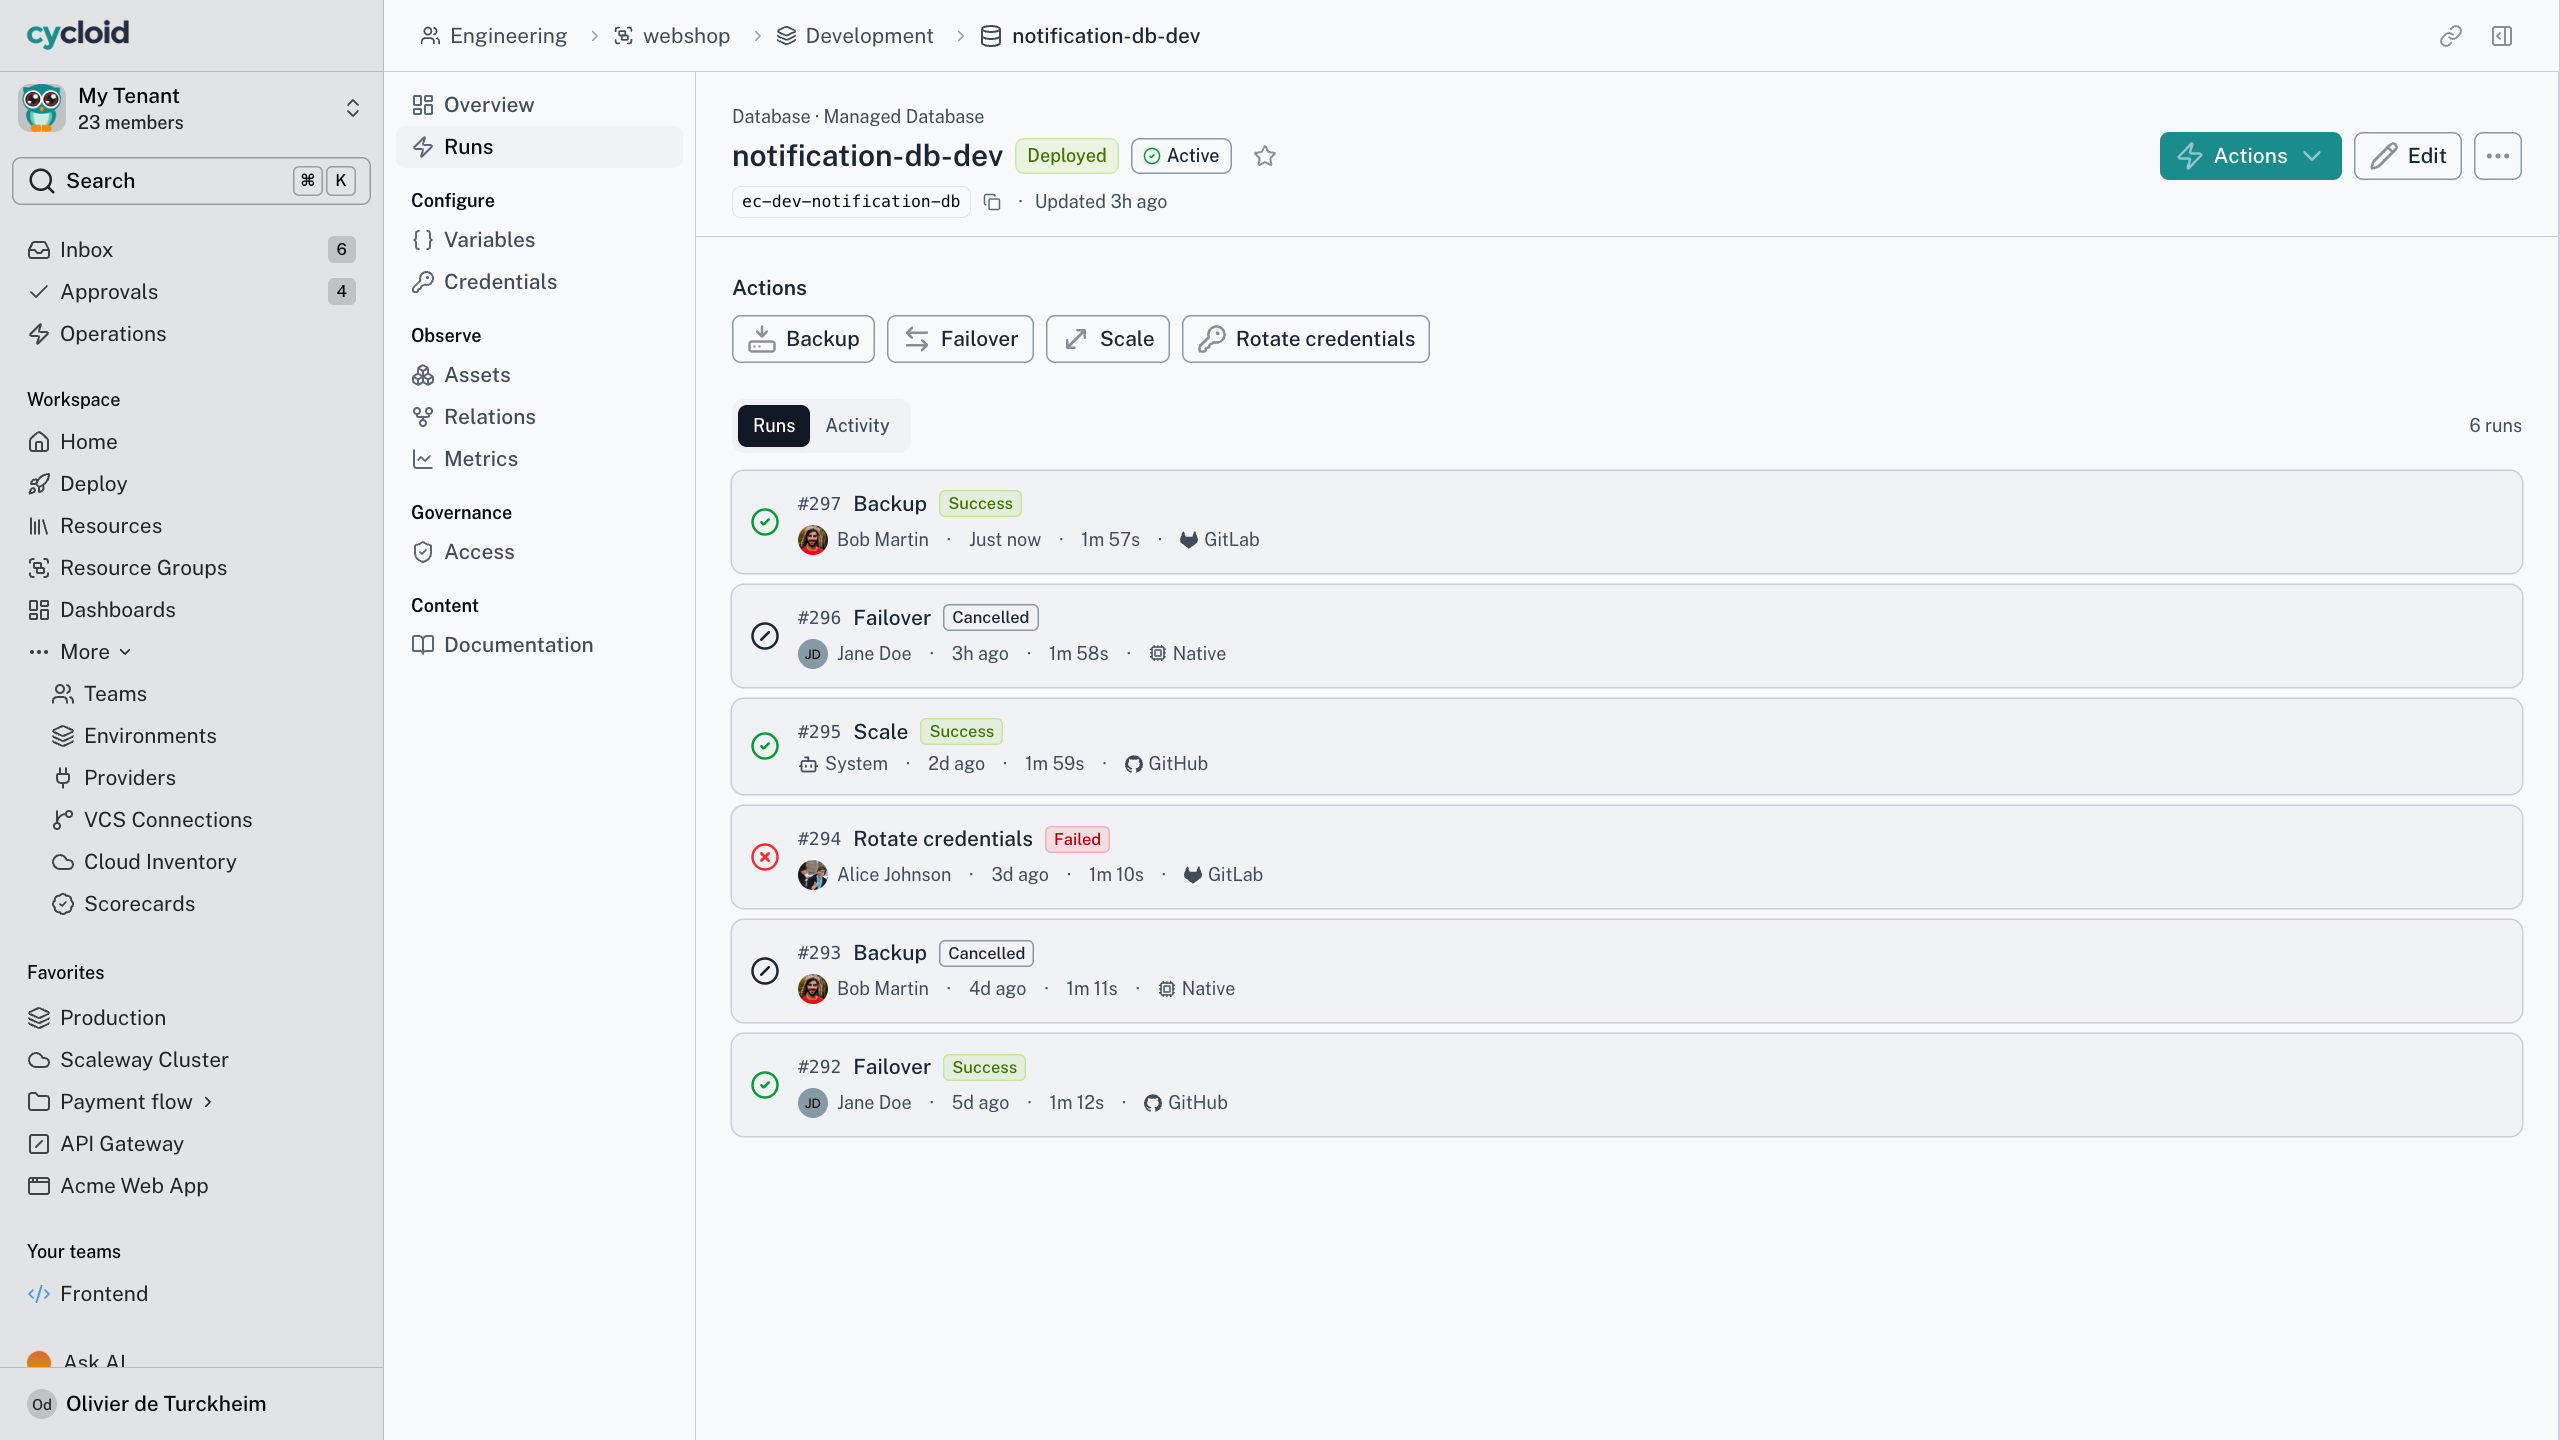
One status view for every pipeline
The second-CI tax
Your CI works. Don't add another.
Most teams have already chosen their CI and built around it. A platform that insists on its own runner and its own pipelines adds cost in three places at once.
Nobody wants a second CI
Your teams standardised on GitHub Actions or GitLab CI. Adopting and securing one more runner is a tax, not a capability.
Infra and app pipelines live apart
The application runs in your CI, the infrastructure runs somewhere else, and the gap between them is exactly where a change slips through.
One run, five status screens
Work spreads across native execution, an external pipeline and a webhook or two. So does the status.
Cycloid for your team
What the Native Runner changes for your team
Orchestrate without running
a second CI
The problem
Every service needing its own pipeline, and scaling and securing the runners, was your problem to carry.
With Cycloid
Actions run on the Native Runner or hand off to the CI you already operate. One coordination layer, not a fleet of pipelines to babysit.
The outcome
You orchestrate infrastructure without standing up a second CI system.
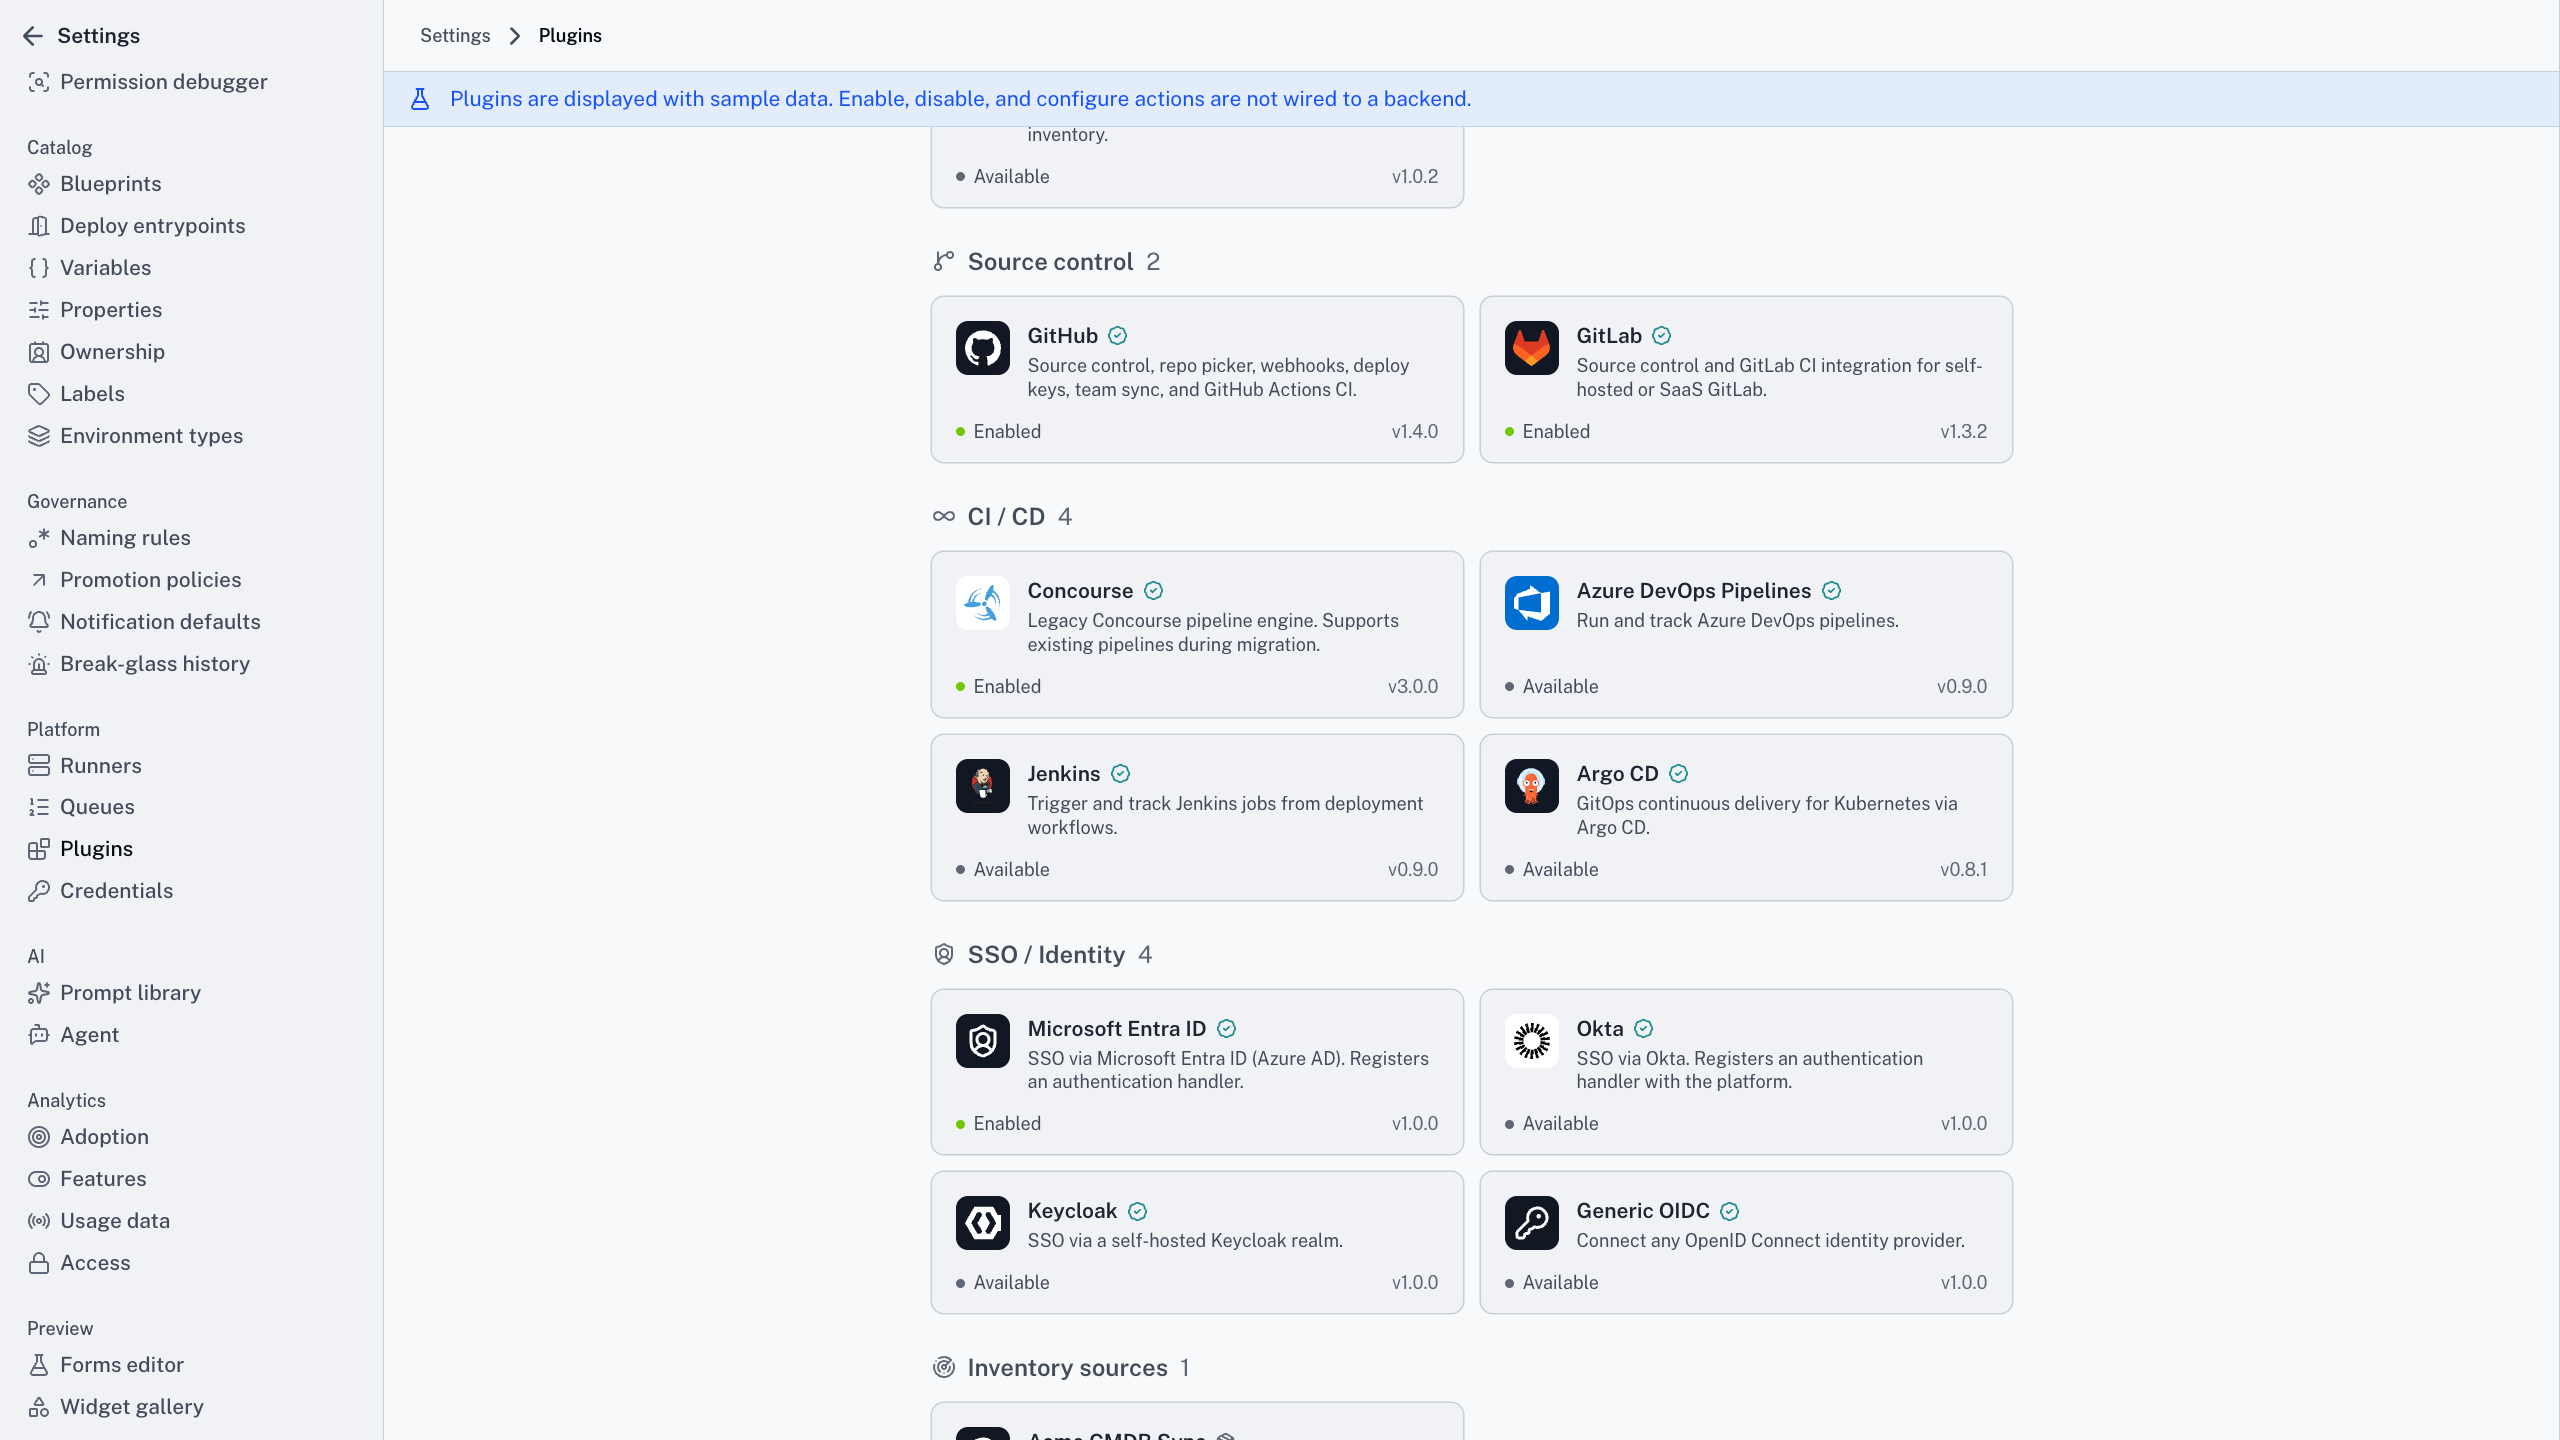
Run infrastructure and
watch it in one place
The problem
Infra runs in one tool, your app pipeline in another, and the status is never in one place.
With Cycloid
Trigger infrastructure from the same platform and watch it next to everything else, native run or external pipeline.
The outcome
One place to run it and see it, not a tab per tool.
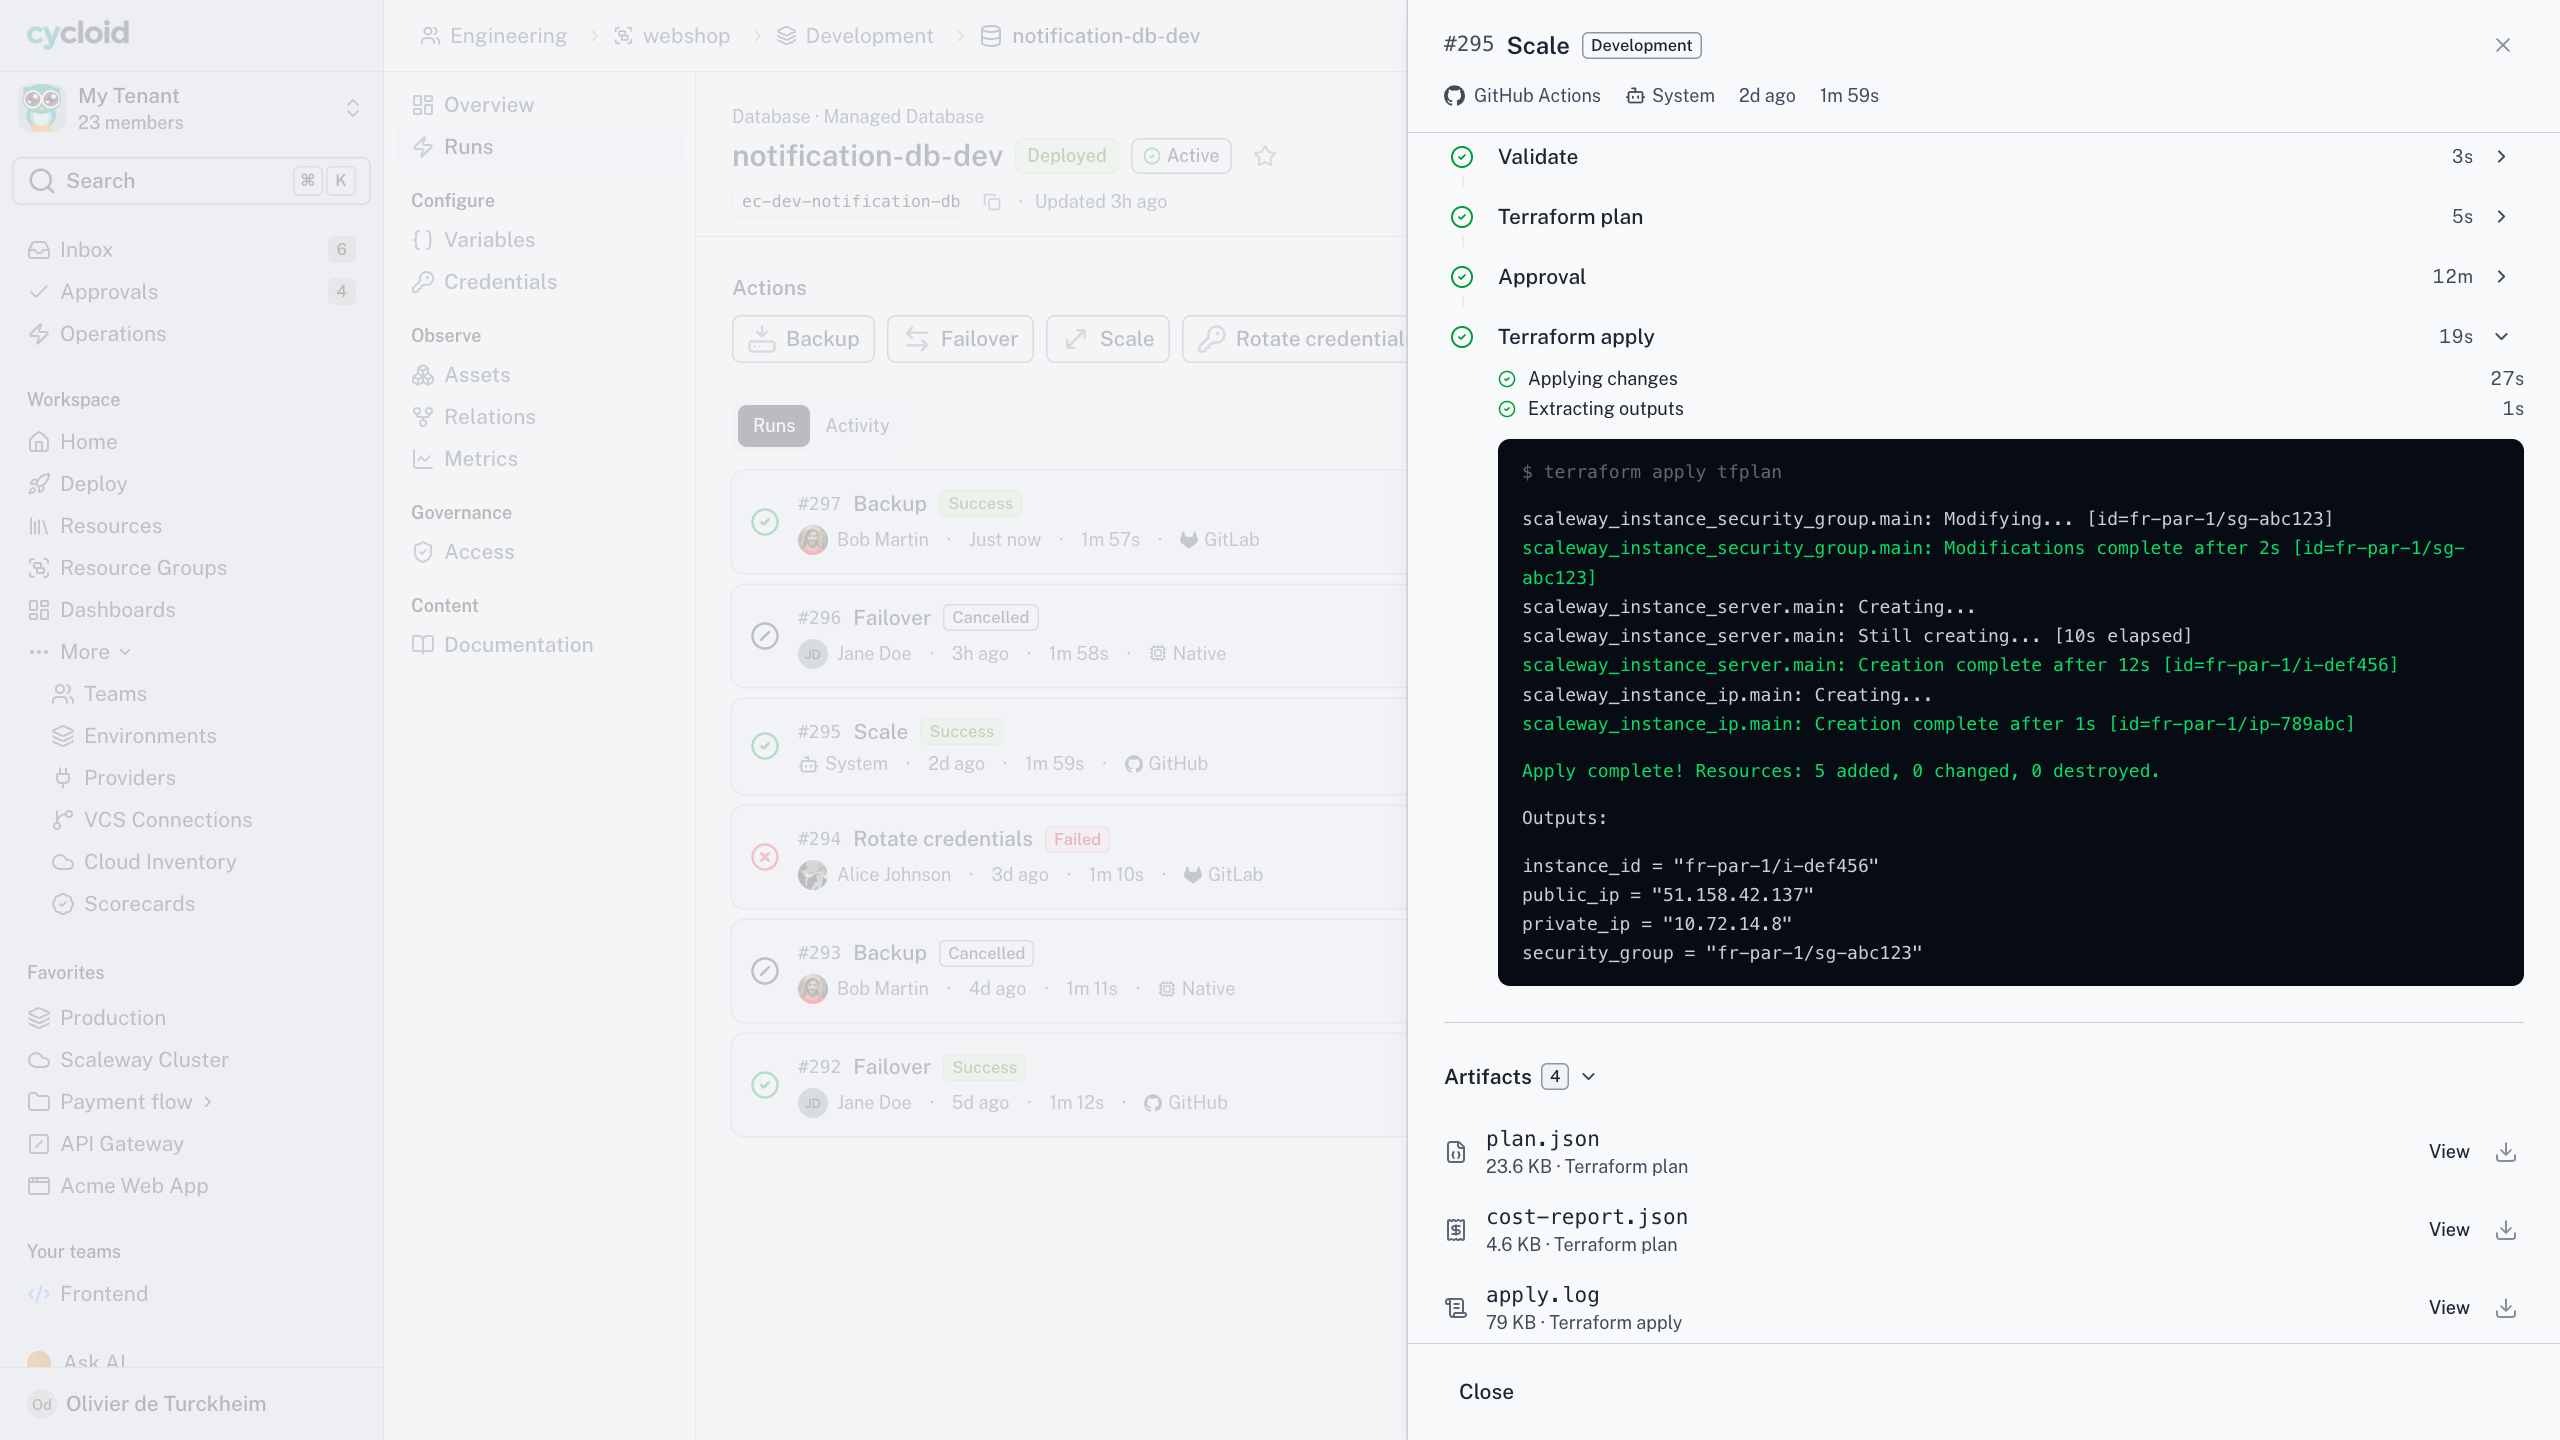
Reuse the CI you've
standardised on
The problem
A second CI/CD system is more cost, more surface to secure and more to own.
With Cycloid
Keep GitHub Actions or GitLab CI, and reach any other CI through an HTTP call. Cycloid coordinates them, it doesn’t compete with them.
The outcome
No rip-and-replace, and no new platform to justify to finance.
How it works
How an Action picks where it runs
01 · An Action declares its backend
Every Blueprint Action names where it runs, whether native, an external pipeline or an HTTP call.
02 · Native, your CI, or an HTTP call
The Native Runner runs Terraform and OpenTofu, Ansible, Helm, scripts and Docker. Or the Action triggers GitHub Actions or GitLab CI, or any CI or API through an HTTP call.
03 · Credentials arrive at run time
Credentials are resolved on submit and injected when the step runs, never baked into a pipeline.
04 · Cycloid coordinates it
Whatever the backend, the platform tracks the state, handles retries and approval gates, and streams the logs.
05 · One status view
The Workflow Status Sync Engine pulls progress, logs and status into one view. A Terraform run and a GitLab pipeline read the same way.
Keep GitHub Actions or GitLab CI for what they’re good at. Cycloid bridges your pipelines, it doesn’t replace them, and it closes the gap between your app pipeline and your infrastructure without asking you to give up either. Splitting the scheduler from stateless workers is what lets the Native Runner scale on its own workers. Concourse pipelines keep running while you move to the Native Runner.
How an Action picks where it runs
The short version
Every pipeline, one view
8
built-in step types, Terraform to approval gates
5–10
deploys a day at Hotel Spider, once manual
1
status view, whatever ran the job
0
credentials baked into a pipeline
Why did last night’s staging deploy fail?
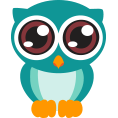
It ran on your GitHub Actions workflow and reported back here.
Run 4821 · deploy · staging
Failed
Backend
GitHub Actions
Failing stage
terraform-apply
Error: quota exceeded for resource type
instance in region fr-par-2 (requested 6, limit 4)
Working with your assistant
Your assistant reads the logs, wherever the job ran
Does the assistant get its own permissions?
No. There’s no service account and no elevated assistant role. If you can’t deploy to production, neither can the assistant you’re talking to, in Cycloid’s own assistant or any compliant MCP host.
Your assistant triggers the Actions you declared and reads status and logs back from whatever ran them. A GitHub Actions run, a GitLab pipeline or the Native Runner. It isn’t a second way to run pipelines. It’s the same coordination layer with a conversation in front of it.
Anything consequential comes back as a preview of what will run and where, and it only runs once you say so.
Frequently asked questions
Do we have to replace GitHub Actions or GitLab CI?
No. An Action can trigger your existing pipeline in GitHub Actions or GitLab CI, or any other CI through an HTTP call, and Cycloid tracks it and streams the logs. The Native Runner is an option, not a mandate.
What can the Native Runner run?
Terraform and OpenTofu, Ansible, Helm, scripts, HTTP calls and Docker steps, across clouds and on-prem. Credentials are injected at execution, so nothing sits in a pipeline definition where it can leak.
Can it run on-prem or air-gapped?
Yes. The Native Runner deploys across clouds and on-prem, and the whole platform runs self-hosted or fully air-gapped. The sovereign page covers how that deployment works, starting from one docker compose up.
How do we see status across backends?
The Workflow Status Sync Engine pulls progress, logs and status from native runs, external CI and webhooks into one API and one UI. A native run and a GitLab pipeline read the same way.
One status view for every pipeline
Bring the pipeline you don’t want to rebuild. In twenty minutes we’ll run a Terraform Action on the Native Runner and trigger one of your existing pipelines, and show them both in the same view.